Why can't searching observability data work like a web search?
It can. Public search engines retrieve information from many sources through applications built on top of search engines. You type a single query and that request is distributed to search engines, databases, or other query engines. Google looks for information in many places, then displays the combined results on a single screen.
So why hasn't the same kind of tool existed for observability? A simple observability data search tool should be straightforward. Yet for years the answer to "where is my data?" has been "which tool did we put it in?"
Federated search comes to observability
Traditional observability tools followed the same model: collect, route, store, and only then search. Cribl applied the web-search model to observability data.
The result is Cribl Search, a federated search tool built for observability and security data. Cribl Search can federate a query to edge nodes, to Amazon S3, to any of your data wherever it lives. You launch the query and results return. Most observability solutions do not have this capability. If you want to search Splunk, you use the Splunk UI and search only what it has already captured. Elastic works the same way. Both tools are useful, but their search is limited to data they have already ingested. Cribl Search can also reach data spread across the enterprise or sitting in your data lake.
Query multiple datasets from a single UI
A dataset is a bounded collection of data: a host, multiple hosts, an S3 bucket, multiple buckets, and so on. Querying multiple datasets from a single UI matters most for things that were never designed to be searchable, like hosts, databases, or object storage.
Cribl Search goes beyond searching data that has already been collected. It gives you access to all your data, wherever it lives. You can search the endpoint itself, which provides visibility into logs, metrics, configuration files, and system state information. That covers what endpoints use to run applications and what they import to run operations.
It is often not cost-effective to collect data from hundreds or thousands of hosts, route it back to a system of analysis, and ingest it just to determine whether it has value. Instead, query the data while it still sits on the edge device, and collect and analyze it only once you've confirmed it's worth the transfer. That is the search-first model, and it pairs with Cribl Edge nodes already running on those hosts.
The old "collect before you search" approach is dated. Cribl Search can also query data that has already been collected, whether it lives in a data lake or an index.
How does Cribl Search access your data?
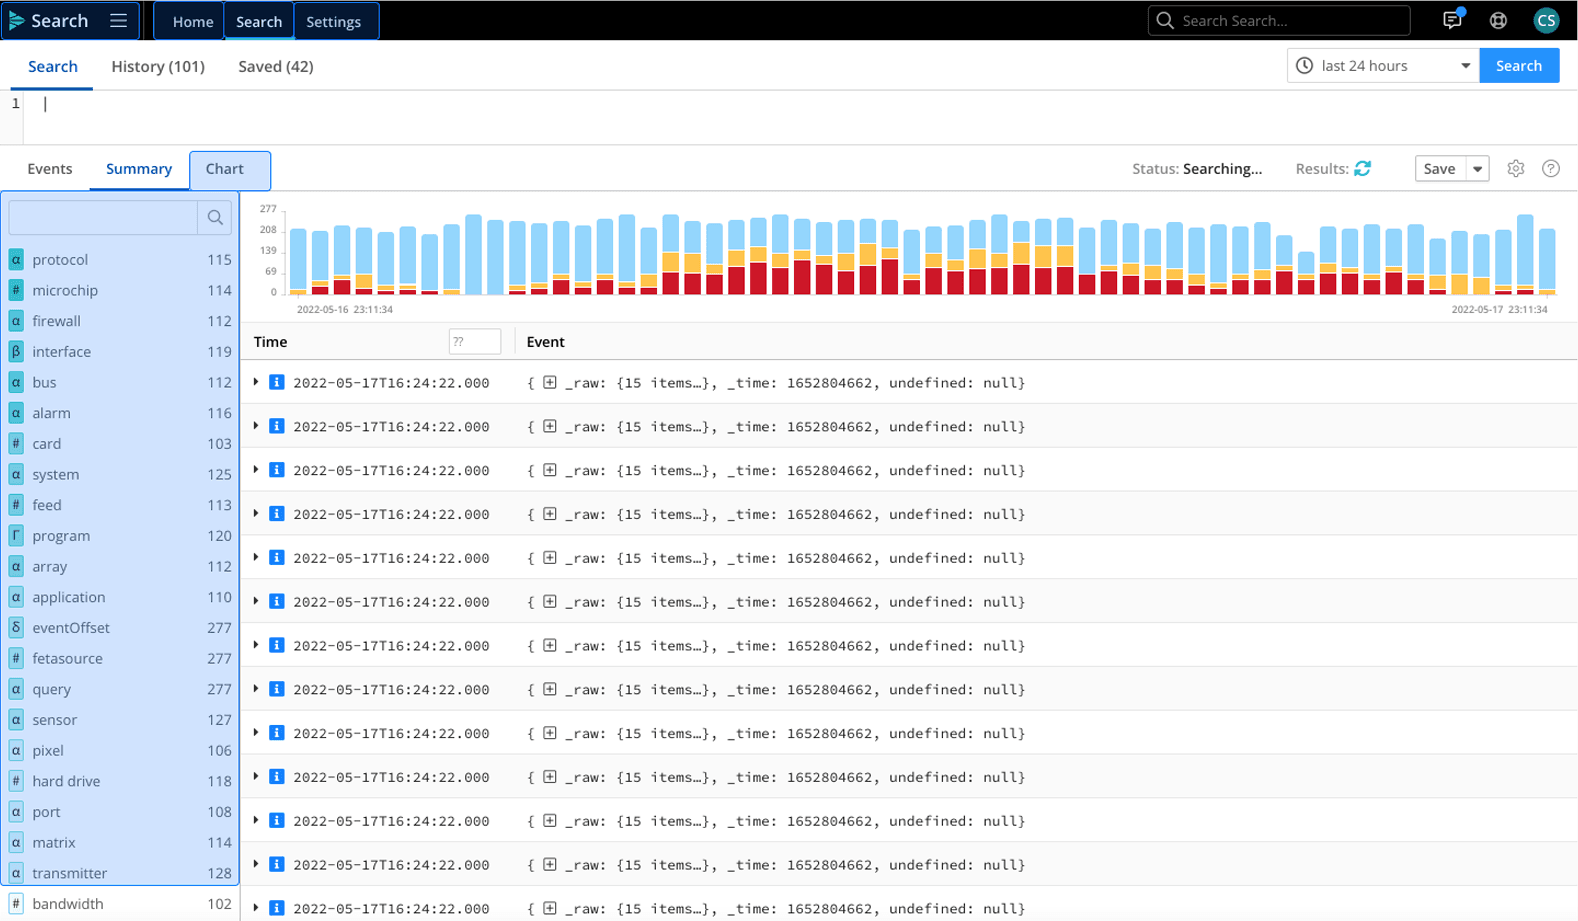
Cribl Search accesses data through datasets, and each dataset defines three things: what to query, where to search, and how to reach the data, including any API keys or credentials required. With Search, you can set access control rules to limit who can query which data, so more people can query data without losing guardrails.
Cribl Search includes predefined common datasets out of the box. You can immediately search leader logs, worker logs, individual Edge nodes, fleets of Edge nodes, and S3 buckets. You can also create your own. A guided wizard walks administrators through defining new datasets so you can get up and running quickly without a deep dive into documentation.
What if you don't know where your data lives?
If you know what you're looking for and where it is, searching is straightforward. The harder, and more common, scenario is when you are not sure where the data is, or when the thing you're hunting could be scattered across your enterprise, your hosts, or your observability lake. What is the best way to search for that?
Select a dataset, or several. Maybe you want to look at specific hosts, workers, or AWS buckets. Or maybe you want every instance of FUBAR across your data. When you launch a search, the scope can be as narrow or as broad as you want. Cribl Search activates query engines where the data sits, whether that's on edge nodes or in AWS, and those engines search through everything as far back as you need.
Results are combined and displayed in the same UI. You see data from many different devices, correlated and timestamped, in one place.
Refine and iterate until you find it
If the first pass returns too much, identify what's useful in the returned results and relaunch the query against them, iterating until you reach the level of detail you need. Search becomes an iterative process rather than a single shot.
With Search added to the suite, Cribl's platform lets you discover, collect, shape, route, and search all from a single UI. One UI shows what is actually going on. Data collected by Edge, processed by Cribl Stream, stored in Cribl Lake, and queried by Search are part of one workflow. For a deeper walkthrough, watch the on-demand webinar on querying data in place.
Cribl Search blog series
The Cribl Search blog series includes "Searching Observability Data Just Became Point & Shoot," "The Most Powerful Tool for Querying Data at Its Source," and "Search Observability Data In-Place: Store Where You Want, Query When You Want."
Ask your data questions where it lives
The initial problem remains for many teams: telemetry volumes keep climbing, formats keep multiplying, and every new tool adds another place data can hide. Cribl, The AI Platform for Telemetry, aims to change that dynamic so your data serves your team instead of the other way around. The vendor-agnostic platform gives IT and Security teams choice, control, and flexibility to manage, investigate, and analyze telemetry for humans and agents, with no lock-in, no data loss, and no compromises.
Cribl Search answers the question "where is it?" It federates queries across edge nodes, object stores, data lakes, and existing indexes, so you can validate what's worth collecting before you pay to move it. Because it works alongside Splunk, Elastic, and other tools you already run, you extend the reach of your current investments rather than replacing them.
The rest of Cribl's suite completes the workflow. Cribl Edge collects at the source, Cribl Stream shapes and routes data in real time, and Cribl Lake provides low-cost, open-format storage that Search can query directly. Together they form the data engine for IT and Security that keeps telemetry portable, interoperable, and searchable at scale across cloud, on-premises, and hybrid environments.
If your team is tired of asking which tool the data went into, start with a free Cribl.Cloud account and point Cribl Search at your first dataset. You can have an answer before you've opened a third UI.
Cribl Search FAQs
What is the difference between federated search and traditional search?
Traditional search requires you to collect, move, and index data into one system before you can query it. Federated search reverses that model by sending queries to multiple data sources simultaneously and returning unified results without moving data.
Does federated search require moving or ingesting data first?
No. Federated search queries data where it lives, whether in cloud object storage, a data lake, or an on-prem system. That avoids rehydration delays, duplicate storage costs, and extra ingestion fees.
What are the main challenges of federated search?
The biggest challenges are data discrepancies between differently structured sources, ranking relevance across sources that use different metrics, supporting advanced query features such as wildcards, and slow or unavailable sources that can delay results.
What are common use cases for federated search?
IT and security teams use federated search for incident investigation across disparate log sources, compliance and audit queries against long-term archives, performance troubleshooting across multi-cloud storage, and analyzing historical data before replaying it to an analysis system.
How does Cribl Search support federated search?
Cribl Search sends queries to the systems where data already lives, including Amazon S3, Azure Blob Storage, Google Cloud Storage, Cribl Lake, and live API endpoints. You use a single search bar and query experience across all sources, and forward only the results that matter to downstream tools.
Is federated search more secure than searching individual databases?
It can be. Federated search reduces direct access to individual databases by providing a governed access layer, so you can apply consistent access controls instead of handing out credentials to every system.