Last month, TypeSafe's Jev showed that a model doesn't need to generate tokens to make good decisions. It emits typed, calibrated answers instead, and that trade is a natural fit for telemetry, where every event is a routing, enrichment, or triage decision made millions of times a day.
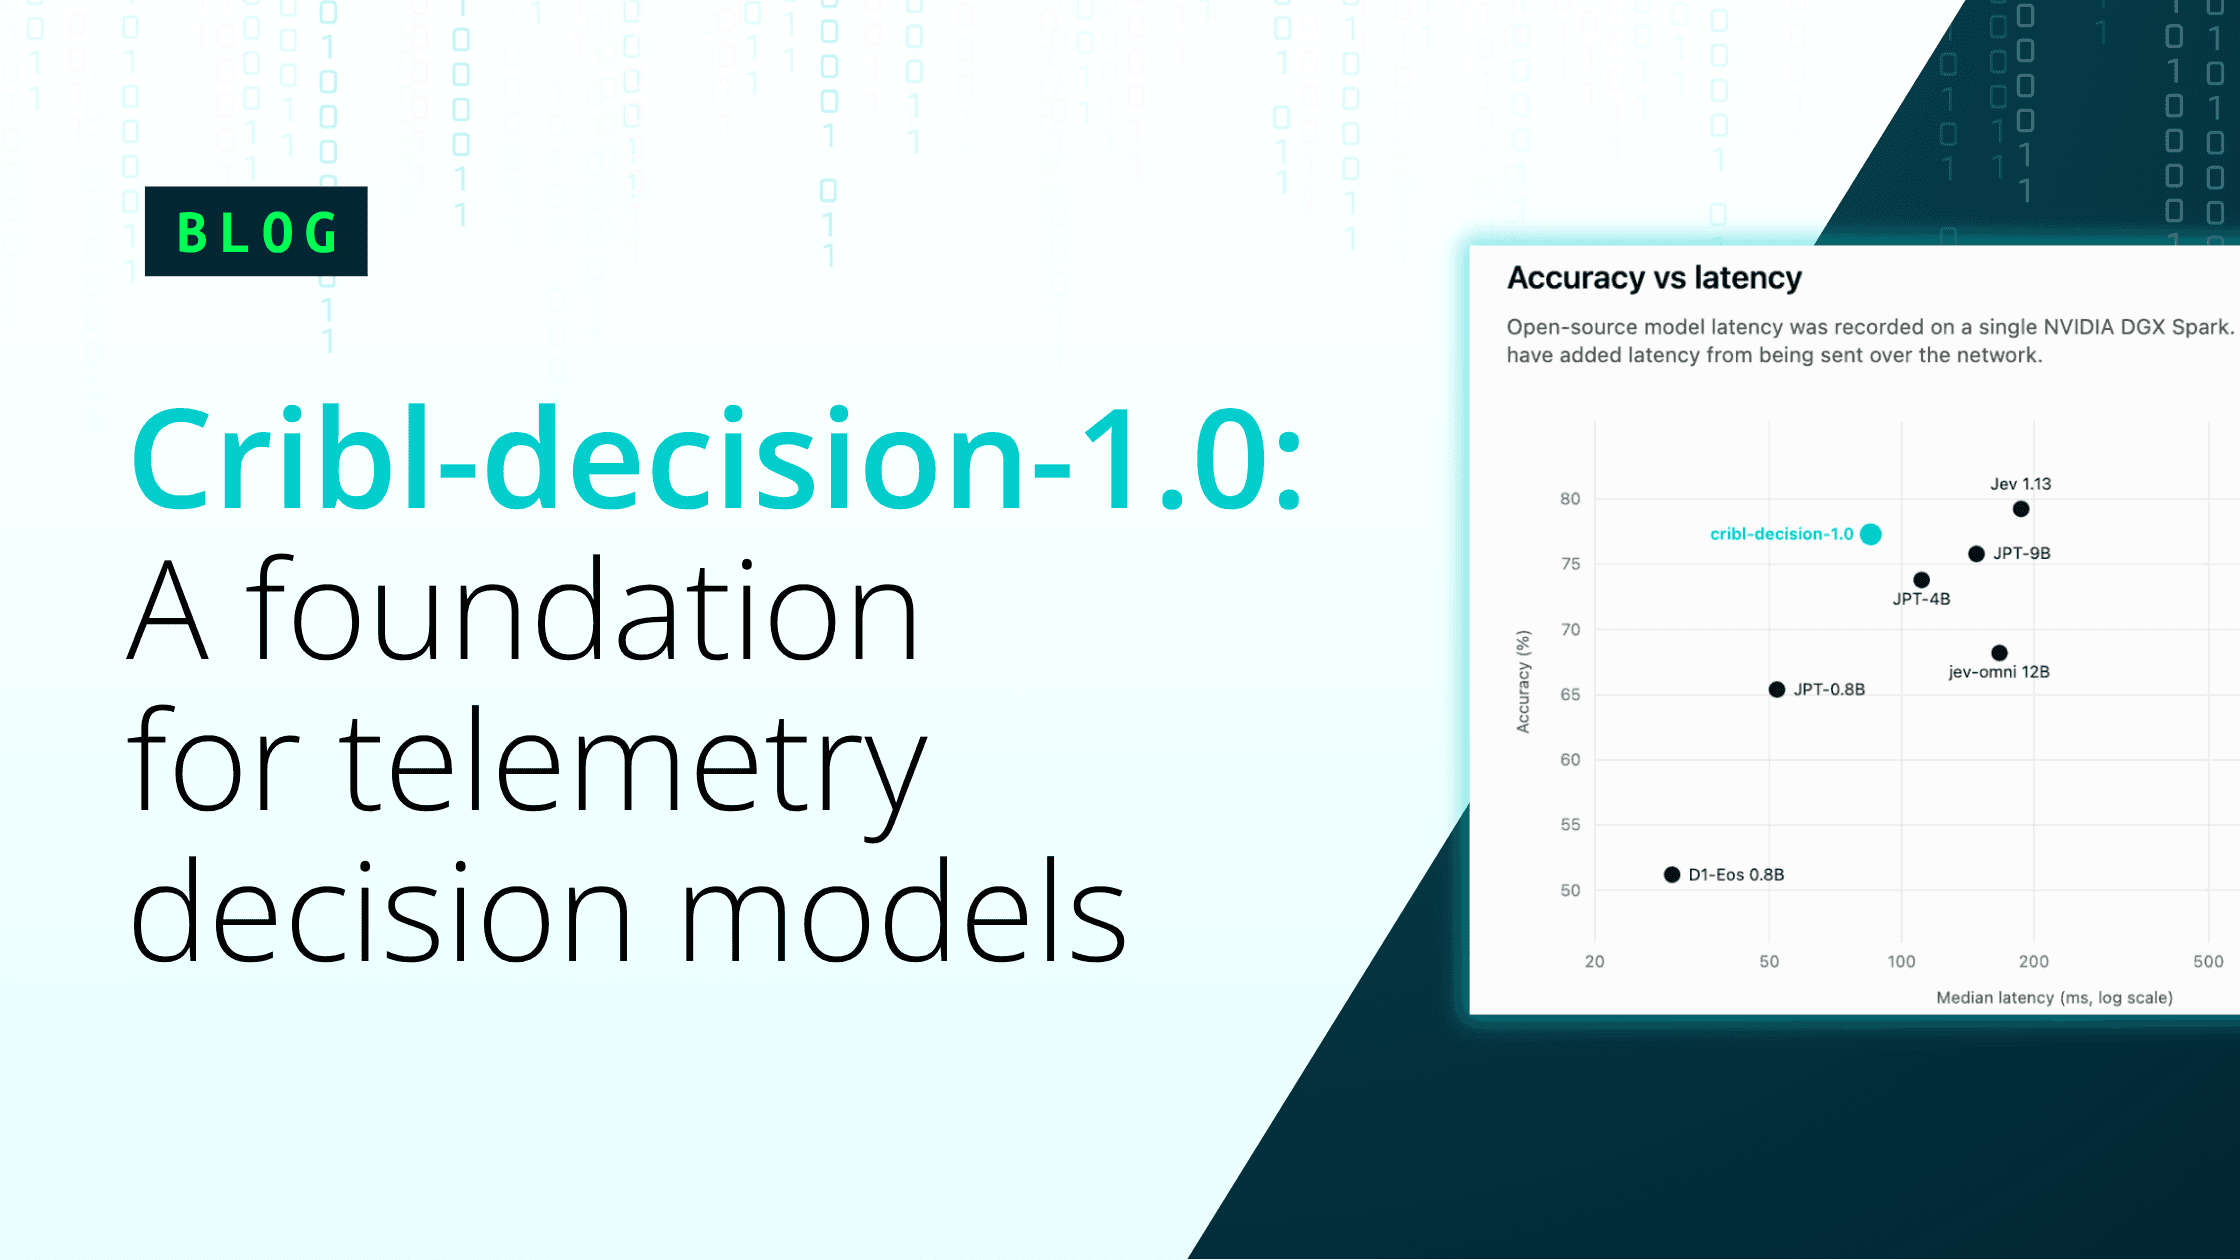
Today we're releasing our own general-purpose classification model: cribl-decision-1.0. This 4 billion parameter, open-weight model is available for anyone to download and run from our Cribl AI HuggingFace page and will be making its way into the StreamAI gateway in the coming months.
Under the hood
cribl-decision-1.0 is a generalized classification model: you give it an input (e.g. a log event, a support ticket, a user request), a question, and the set of options to choose from, and it returns a probability for every option. It doesn’t generate free-form text like you might expect from an LLM. Instead, it reads the answer straight from a single forward pass, so every response is one of the options you supplied, with a confidence score attached.
It’s is a LoRA fine-tune of Qwen3.5-4B-Base trained on more than 1.5 million records drawn from a broad mix of decision tasks: text classification, intent routing, preference and quality judgments, safety, knowledge QA, reasoning, agent and tool selection, and programmatic rule families. Because the label set arrives with every request, the model learns how to make a bounded decision rather than memorizing any one label set.
Evaluation
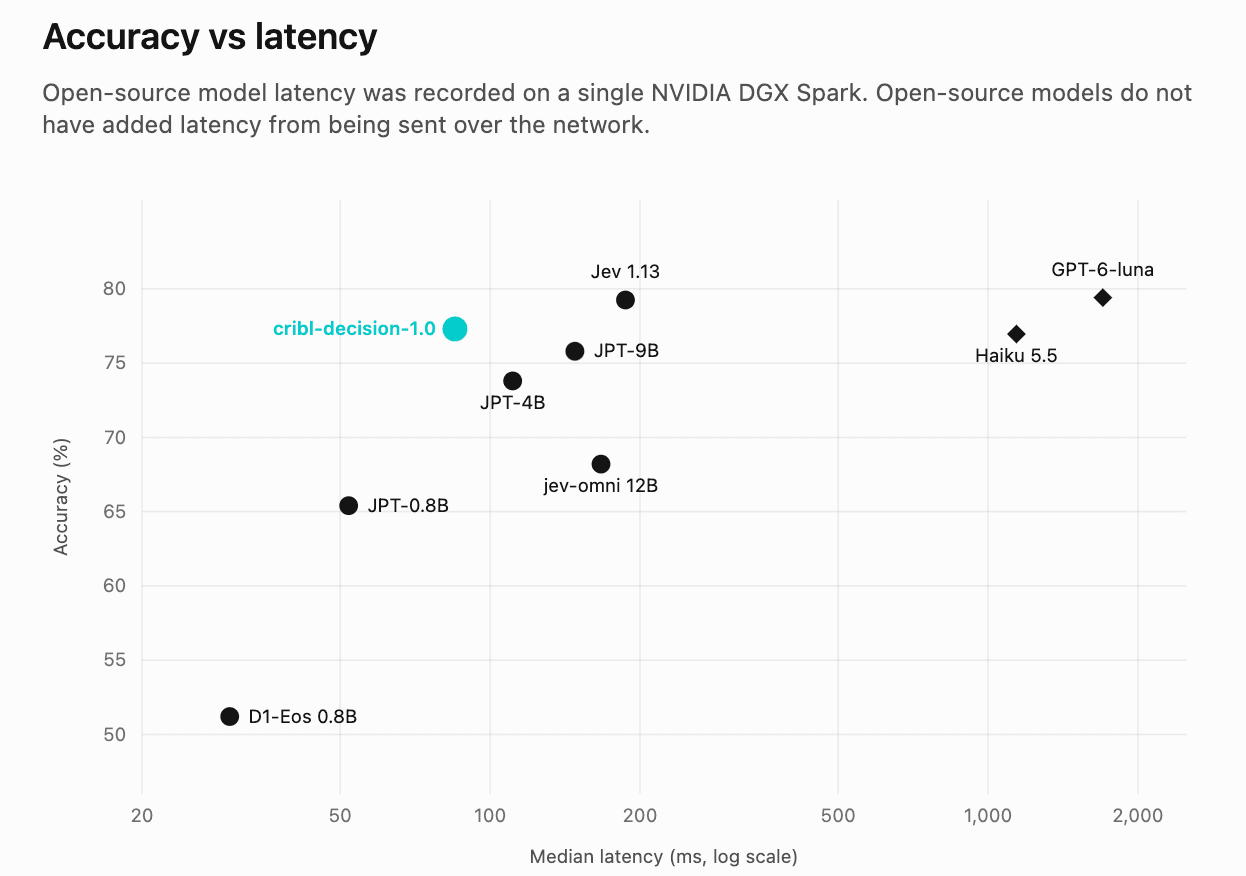
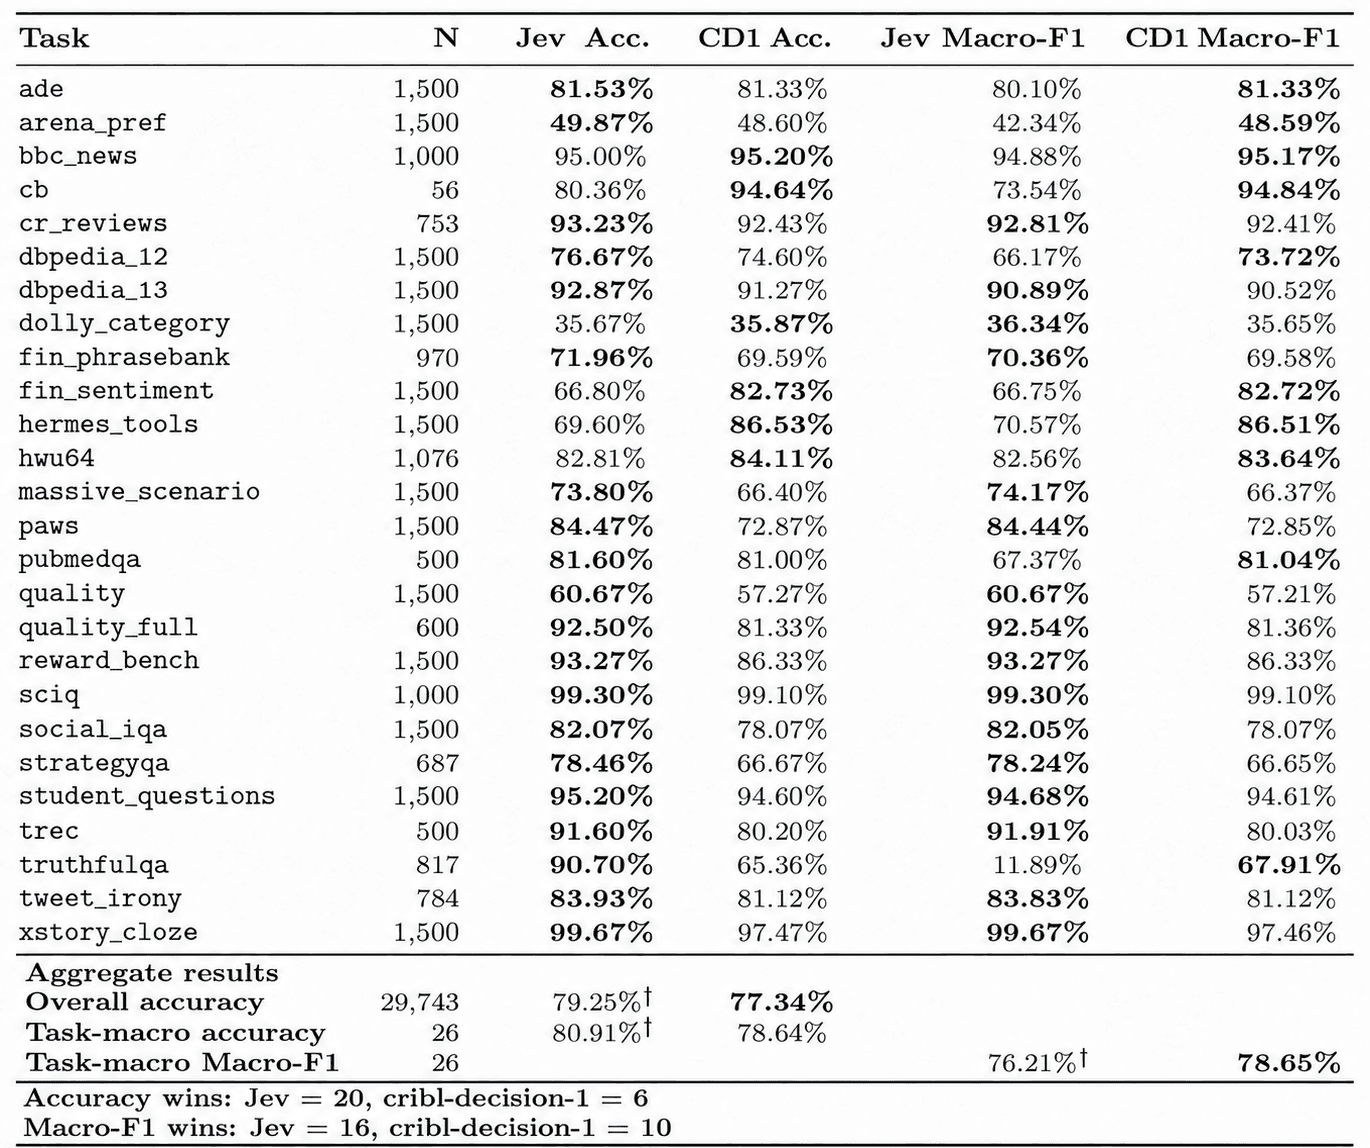
On a 26-task held-out benchmark (29,743 records, none of them seen during training or checkpoint selection) it scores 77.3% overall accuracy, 78.6% task-averaged accuracy and 78.7% macro-F1. It beats Jev outright on 6-10 of the 26 tasks and tracks closely on the rest, while outperforming other open source models we tested.
What's next
cribl-decision-1.0 shows what a small, general-purpose decision model can do, and gives us the foundation to build models purpose-built for the IT, security, and telemetry world. Here’s what’s coming next:
A smaller + faster version of cribl-decision. 800 million parameters.
A benchmark for decision models on IT, security, and telemetry tasks. General classification benchmarks don't capture the messy, semi-structured data our customers deal with every day. We're building one that does, so anyone can measure how well a decision model holds up on real telemetry work.
A domain-tuned crib-decision. A version of the model trained specifically on the IT, security, and telemetry tasks that matter most to our customers and partners.
In the meantime, grab the weights [here] and let us know what you think.
And if this is the kind of problem you like working on, we're hiring.