AI traffic is quickly becoming another critical enterprise data flow. Employees are using chat assistants, developers are embedding AI into applications, and agents can make thousands of requests without a person reviewing each one. As that activity scales, the questions start to look a lot like the ones IT and security teams already ask about the rest of their environment: Where is sensitive data going? Which systems can access it? What is it costing? And when something goes wrong, how do you trace what happened?
That is a big part of why I wanted us to build Cribl StreamAI, our secure enterprise AI gateway, as part of the Cribl platform. If AI traffic is becoming part of enterprise infrastructure, it doesn’t make sense to manage it in a separate silo. The context you need to understand AI activity already exists across identity systems, endpoints, applications, infrastructure, and security tools.
Cribl StreamAI is built for those teams. It routes requests across models, applies security and spending controls, and turns model activity into telemetry that can be connected to the enterprise data the Cribl platform already manages. That brings AI traffic into the same operational picture IT and security teams already use to protect the business, alongside the data that gives that activity context.
Isolation that fits the way enterprises buy cloud software
As AI moves deeper into production, the architecture behind the gateway matters more. AI gateways handle prompts, responses, credentials, and usage records, so one of the first questions enterprises ask is where that traffic is processed and what infrastructure it shares with other customers. A shared service can be easy to get started with, but security teams want clear boundaries around access and data. Operations teams also care about noisy neighbors, contention, and unpredictable performance.
Cribl StreamAI benefits from the Cribl.Cloud architecture customers already use for Cribl Stream and other Cribl products. Core product services run per organization in a dedicated AWS account, while Cribl operates a shared management plane. That gives each organization a distinct account boundary for its product infrastructure. AWS recommends account separation because it creates a strong boundary for security and access.
That makes it easier for teams to understand which infrastructure is handling their workloads and gives them a deployment model they already know as they bring more AI into production. To me, this is part of the broader shift happening around enterprise AI. As AI becomes core infrastructure, the controls around it need to look more like the controls enterprises already expect elsewhere.
Every model call becomes useful telemetry
An AI gateway sees a lot more than token spend. It knows which application made a request, which model handled it, how much it used, what it cost, and how the routing decision was made. That is useful data, especially when you can connect it to everything else happening across the environment.
Cribl StreamAI records model calls and routing decisions as normalized telemetry. Teams can use that data to investigate an unexpected cost spike, audit model usage, or understand why an application started behaving differently. Because that telemetry is already part of the Cribl platform, teams can use Cribl Stream to filter, enrich, transform, and route it alongside the rest of their operational data. They can shape events for the tools they already use, including OCSF, UDM, ECS, or a custom schema, then send the right records to a SIEM, observability platform, archive, or somewhere else.
Cribl Search gives teams a lakehouse engine to rapidly investigate AI activity across that broader telemetry estate. Or, for a purpose-built experience, the Cribl App for AI Observability gives teams a focused view into AI usage, performance, and cost without separating that activity from the broader telemetry platform.
This is one of the reasons I think the AI gateway and telemetry layer belong together. Otherwise, you end up creating a new source of valuable data only to turn around and figure out how to connect it back to the rest of the enterprise. That feels backwards. The gateway should sit with the important data flows in the enterprise, and the data it creates should be immediately useful.
AI activity is more useful with enterprise context
Cribl Stream already brings together security data from sources like Microsoft Entra activity through Azure Event Hubs, syslog from Linux hosts and network devices, CrowdStrike FDR, and AWS CloudTrail or VPC Flow Logs. Now imagine inference records flowing alongside that data.
A developer might sign in from an unusual location and then generate a burst of requests through a coding assistant. The inference records can tell you which application and model were involved, when the requests happened, and how much was used. Entra can give you identity context, while endpoint or Linux logs can help show what was happening on the device.
With Cribl Search, teams can investigate that activity across AI, identity, endpoint, and infrastructure data using the same lakehouse engine they use for the rest of their telemetry, or send the enriched data to their existing SIEM or log analytics tool. Put that together and a token spike is no longer just a token spike. It becomes part of a timeline involving a user, a device, an AI application, and the surrounding activity.
That is the difference between seeing AI activity and actually understanding it. The inference logs from an AI gateway can tell you what happened between an application and a model. The rest of your telemetry helps tell you what it means.
Some teams may also need to examine text submitted to a chat assistant or code sent to a model. When enabled, Cribl Stream can apply redaction, filtering, and routing policies so sensitive content reaches only approved destinations. Teams can keep detailed records where they need them while sending leaner, normalized events to tools used for high-volume detection and reporting.
Build on the combined data
Once those records are searchable, Cribl Apps can turn them into workflows built around a team’s needs. A security app could show model use alongside unusual sign-ins and endpoint activity, flag an unexpected AI request following a risky login, and help an analyst assemble a timeline. An operations app could track latency, errors, and spending by application while linking an incident back to the relevant host and service logs.
The same pipeline can send enriched records to a SIEM, retain fuller detail in a lower-cost destination, and make that data available in Cribl Search or Lake for custom apps. The point is not just to collect another category of logs. It is to make AI activity more useful by connecting it to the context enterprises already have, then give teams focused experiences for their own workflows to investigate and act on that combined picture.
Make cost controls part of the workflow
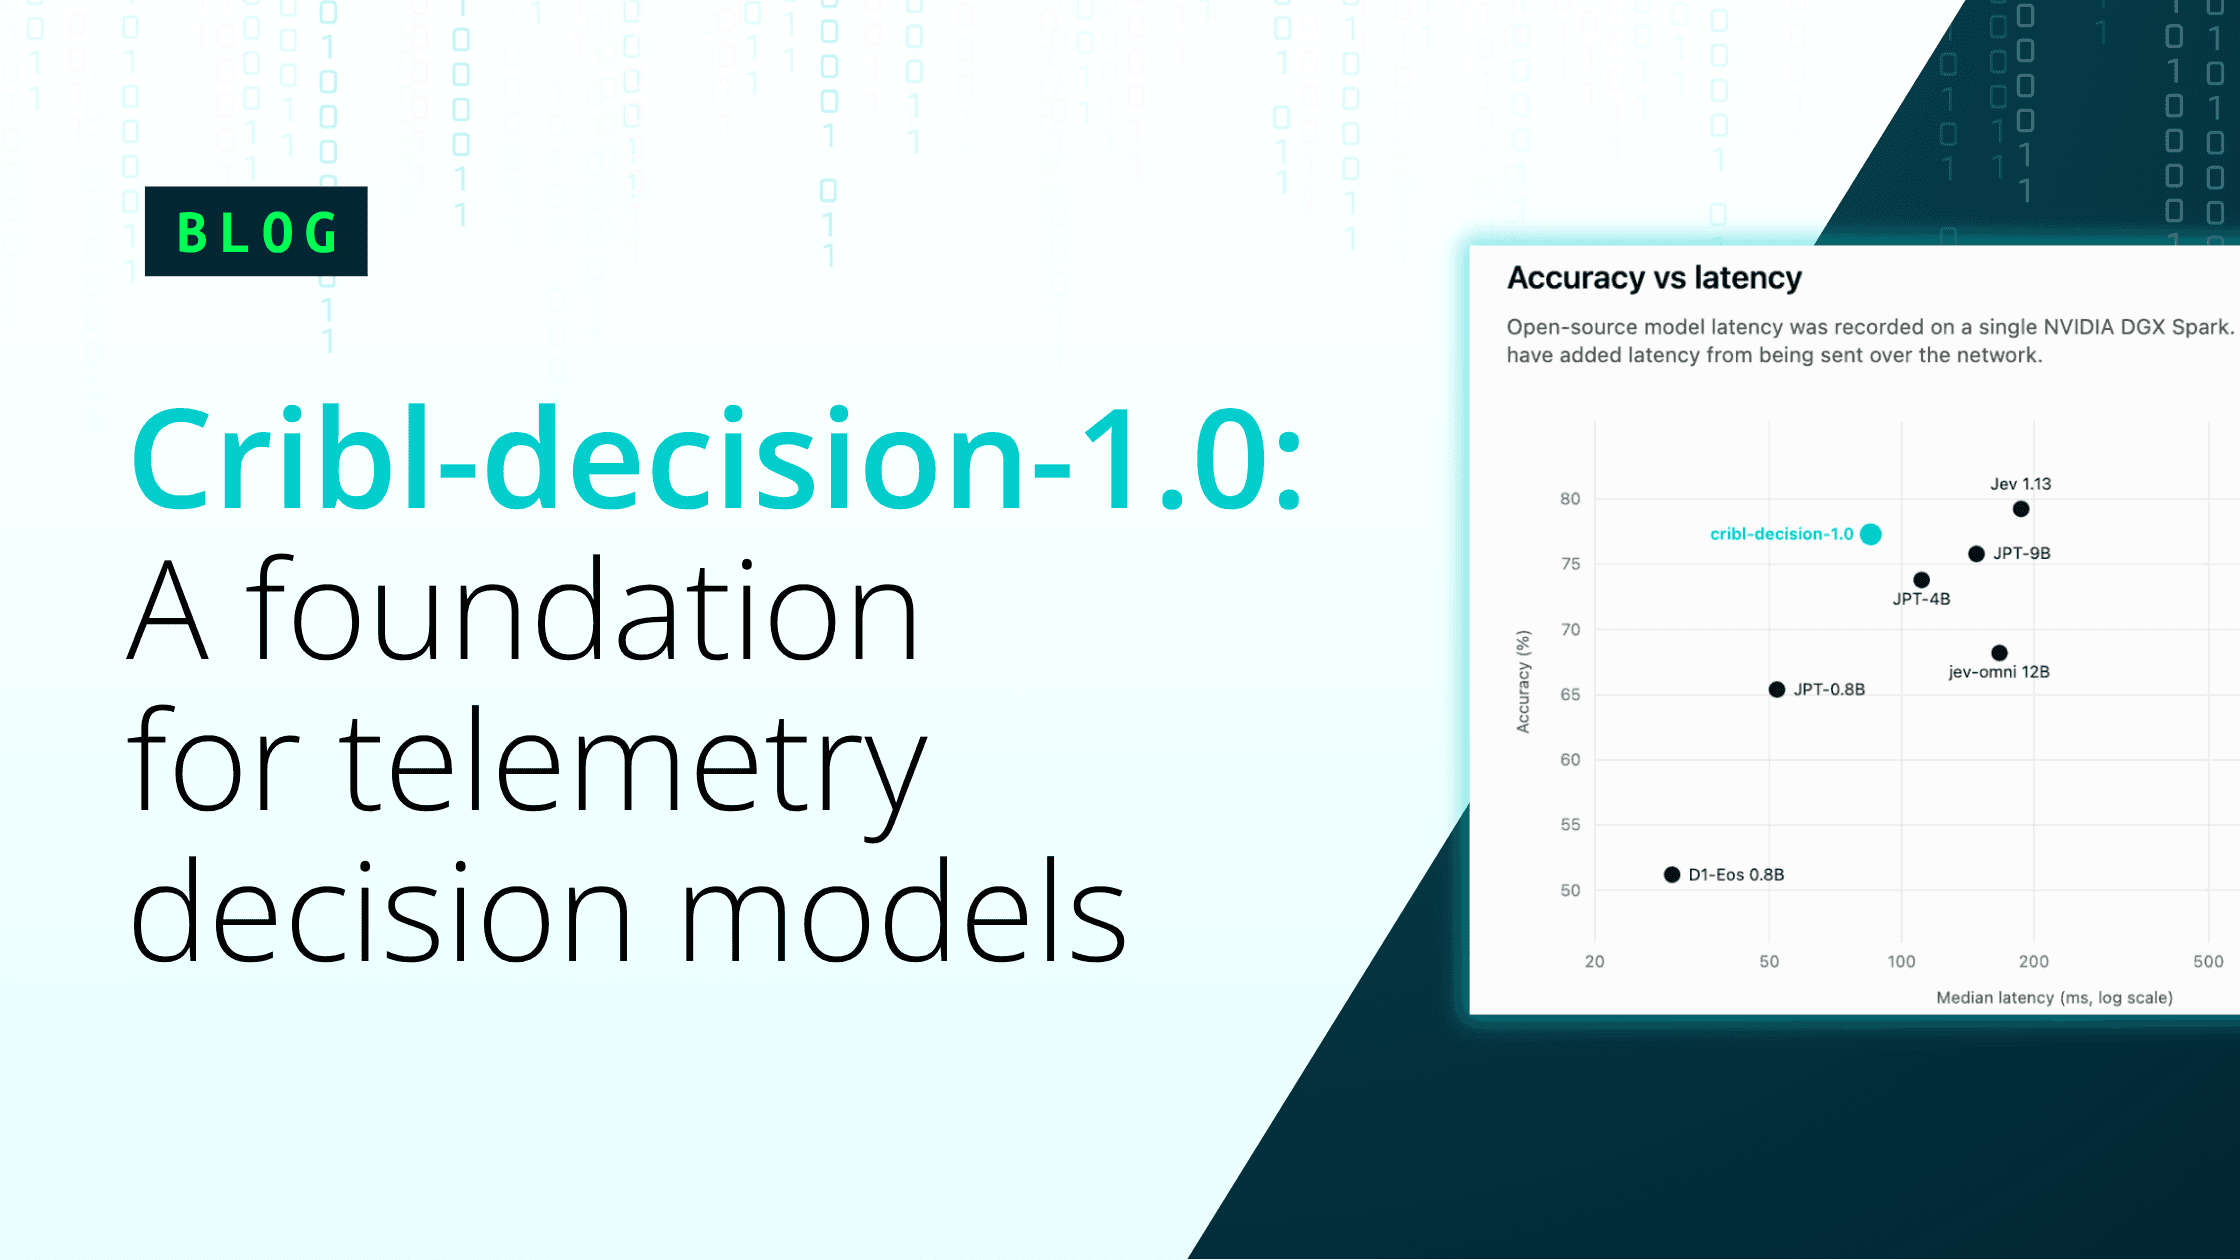
The same idea applies to model choice and cost. One thing our Cribl AI Research Lab has seen through SecIT Bench is that there is no single model that is best at every task. Models perform differently depending on the workload, and those differences matter when you are balancing quality, performance, and price.
That research helps inform smart routing in Cribl StreamAI. Rather than hard-coding every application to a single model, Cribl StreamAI can route requests based on the task and its economics, while built-in budgets and spending cutoffs help keep an agent or application from running away with token spend.
Teams can then use the resulting usage data to understand where that spend is coming from and, when the right ownership metadata is available, attribute it back to an application, team, or business unit. That becomes much more important as AI shifts from people occasionally prompting a model to applications and agents making requests continuously.
At that point, model choice, cost, security, and performance are no longer just concerns for the team building the AI application. They become operational concerns.
Bringing AI into the operational picture
And that is really the broader idea behind Cribl StreamAI. Enterprises have spent years building ways to collect telemetry, add context to it, protect sensitive data, route it where it needs to go, and manage the cost of all of it. AI traffic needs many of those same things.
The next phase of enterprise AI will be less about adding standalone AI infrastructure and more about bringing AI into the systems enterprises already use to operate the business. That is what we are building toward with Cribl StreamAI: managing the traffic between applications and models while making that activity part of the same platform teams already use to understand and manage the rest of their environment.