What is observability data?
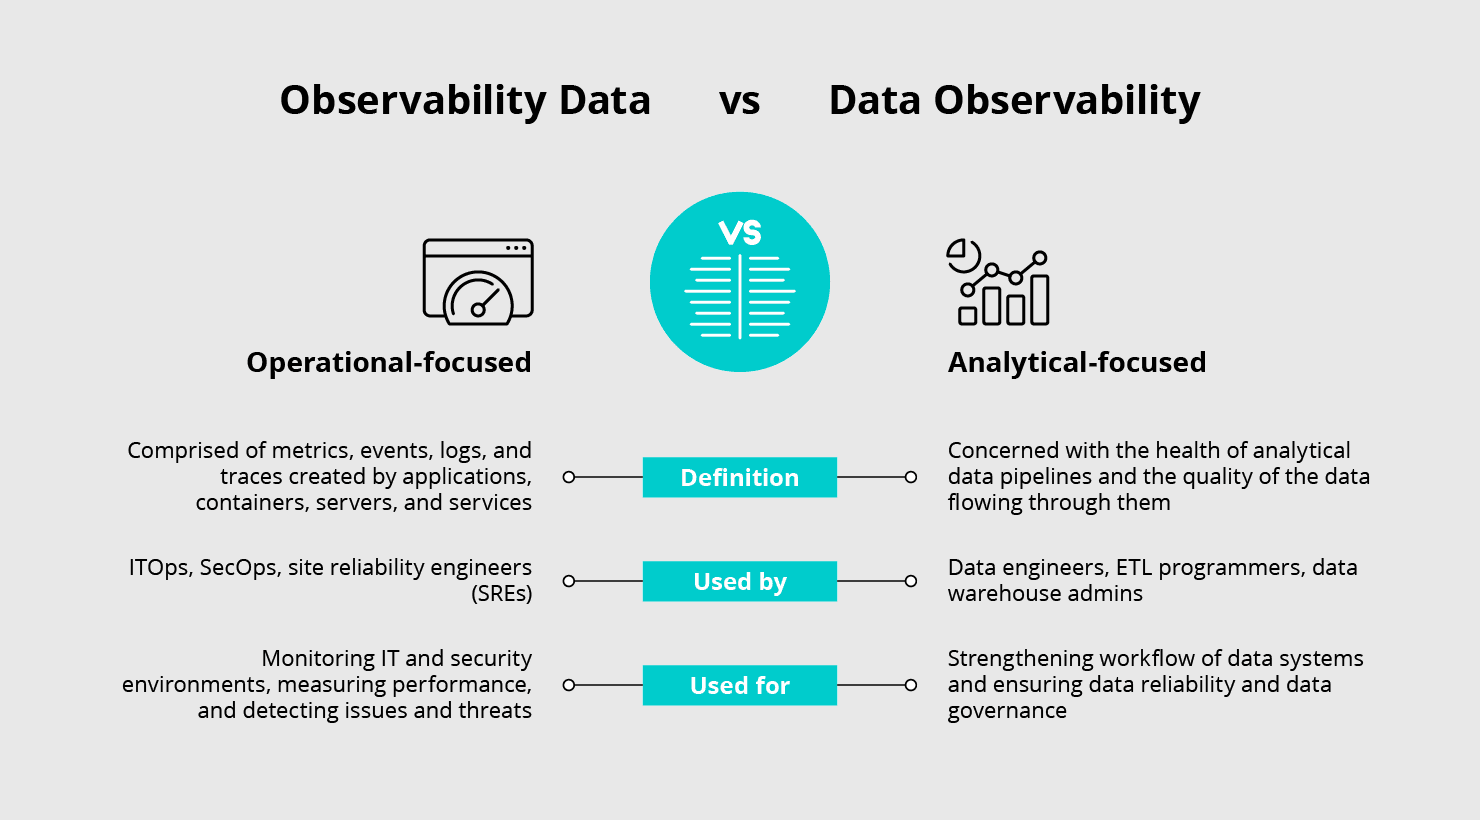
Observability data is the metrics, events, logs, and traces that other forms of observability and monitoring depend on. It is the operational exhaust created by applications, containers, servers, and services. Security operations teams, IT operations and monitoring teams, and site reliability engineers (SREs) use it to understand environments, measure performance, and detect security threats.
Despite being a byproduct of other work, observability data volumes often dwarf other data sources, like transactional data. In cloud-native environments, most organizations generate more than five to 10 TB of telemetry daily, especially log data, according to Gartner, 2024. Those volumes are large.
Transactional data is where the related concept comes in.
What is data observability?
Data observability focuses on two things: the health of analytical data pipelines and the quality of the data flowing through them. In a typical analytics environment, the pipeline moving data from operational databases (for example MongoDB or SQL Server) to analytical data warehouses (for example Snowflake or Teradata) can include dozens of different tools. When one tool fails, or the data changes shape, it can derail the long-running batch processes that drive strategic analysis.
Data observability is typically owned by data engineers, ETL programmers, and data warehouse administrators. Monte Carlo, whose CTO Lior Gavish discussed the category on The Stream Life podcast, is one of the companies defining this area.
Which one is right for you?
It depends on your role.
If you're a chief data officer or chief analytics officer, a strong data observability practice increases the reliability of your data pipelines and helps build trust in your data products across the enterprise.
If you're an IT or security leader, you need a strategy to handle the volume of observability data flooding your platforms. Collecting the right data and delivering it to the right systems affects customer experience and the ability to detect and prevent security incidents.
Why are both concepts gaining ground?
Enterprises are recognizing the value of healthy, usable observability data. Demand for data scientists, data engineers, and observability engineers keeps climbing, and chief data officers are more prominent. Observability data provides the insights that support organizational goals and help teams detect fraud and threats early. As volumes grow, systems are needed to capture, store, and analyze the right data to make informed decisions.
Cribl Stream was built to address that problem. It is a vendor-agnostic pipeline that collects, reduces, enriches, normalizes, and routes observability data from any source to any destination.
Data observability, by contrast, gives engineering teams visibility and control over a diverse analytical data infrastructure. It lets them manage, monitor, and resolve issues across the layers of a distributed data stack, using insights extracted from the data the organization is already collecting and processing.
Both target different markets, use cases, and timeframes. Observability data supports teams that need efficient, real-time routing of telemetry. Data observability supports teams that need trust in their analytical data. Both help organizations realize more value from data they already generate.
What markets do they serve?
In a Stream Life podcast episode, Nick Heudecker, Senior Director of Marketing Strategy at Cribl, and Lior Gavish, CTO at Monte Carlo, discussed the markets for both. One takeaway: cloud adoption and system complexity are increasing, which makes it harder to build reliable microservices and maintain a clear security posture. Both rely heavily on data and analytics.
The observability data market
Observability data helps organizations manage assets, services, and data flows. This market is more mature than data observability. Companies like Cribl offer approaches that let the same data feed multiple tools and destinations for different use cases, without locking organizations into a single vendor. The market is built on logs, events, metrics, and traces, and that data grows over time. Organizations keep investing here to manage environment complexity and support business decisions.
The data observability market
Data observability tools serve data engineers, data architects, chief data officers, data scientists, and analytics leaders. As more business functions become digital, these teams rely on analytical data to make decisions. That data must be reliable to be useful, and data engineering teams need observability tooling to meet SLAs and build trust in data products.
How do their advantages differ?
Data observability helps data engineering teams ensure reliability and governance. The stack centers on data warehouses. Information from these platforms is collected, optimized, and presented to data engineers, helping them strengthen workflows across their data systems. The focus is understanding the data flowing through the system.
Observability data supports infrastructure and cybersecurity teams. They collect the data to monitor what is happening across their environment, and they increasingly monitor the health of the observability pipeline itself. The focus is understanding the environment the data describes.
Here is a comparison:
Why they overlap
Observability is widely adopted in IT. Both observability data and data observability address different aspects of the data lifecycle. Data observability covers the collection, storage, analysis, and visualization of organizational data for analytics. Observability data is about routing telemetry to the right places, in the right shape, at the right time.
Observability data is operations-focused. It helps monitor and manage data flows, confirm infrastructure and services are functioning, and spot routing or pipeline performance issues before they affect overall data health.
Data observability is analytical. It gives data teams a deeper view of the quality, structure, and distribution of the data in their systems. It also helps optimize pipelines, improve reliability and governance, and detect anomalies in the data.
Evaluate your data needs and decide which approach fits which team. Observability data and data observability are complementary, and used together they help teams across the enterprise get more value from their data.
Make the exhaust work for you
This is where the two worlds meet. Data observability teams can trust their warehouses, but if IT and security telemetry is scattered across many tools and formats, that trust erodes. Cribl's position is that telemetry should serve teams, not the other way around. Cribl provides tools, built on its Data Engine for IT and Security, that let enterprises control and analyze telemetry for both humans and agents, without vendor lock-in or data loss.
It starts with the pipeline. Cribl Stream sits between sources and destinations, so you decide what to collect, how to shape it, and where it goes. Reduce noisy logs before they reach your SIEM. Enrich events with context analysts need. Route a full-fidelity copy to low-cost storage and replay it later. Because Stream is vendor-agnostic, you can onboard a new tool or migrate off an old one without re-architecting.
The rest of the suite extends that control across the environment. Cribl Edge handles distributed collection at the source, so you can discover and filter telemetry on the hosts that generate it. Cribl Search lets you query data in place, across object stores and edge nodes, without collecting and indexing it first. Cribl Lake provides tiered storage in open formats, so older telemetry remains searchable when a new incident occurs. Together they form a single, vendor-agnostic hub for the observability data IT and security teams rely on.
You can create a free Cribl.Cloud account and process up to 1TB a day at no cost, or try a guided Cribl sandbox with sample data already loaded.
Observability Data vs Data Observability FAQs
What is the difference between observability data and data observability?
Observability data is the raw telemetry: the logs, metrics, events, and traces emitted by applications, containers, servers, and services. Data observability is the practice of monitoring analytical data pipelines and the quality of the data they carry. One is a type of data, the other is a discipline for keeping data trustworthy.
Who uses observability data?
Security operations, IT operations and monitoring teams, and site reliability engineers (SREs) rely on observability data to understand their environments, measure performance, and detect security threats. They typically use SIEMs, APM tools, log analytics platforms, and low-cost object storage.
Who uses data observability?
Data engineers, ETL programmers, data warehouse administrators, data architects, and chief data officers use data observability tools. Their goal is to ensure the pipelines feeding analytical data warehouses like Snowflake or Teradata run reliably and deliver data the business can trust.
Is data observability more mature than observability data?
No. On the Stream Life podcast, Nick Heudecker of Cribl and Lior Gavish of Monte Carlo agreed that the observability data market is more mature. Data observability is a newer category that emerged as businesses started making strategic decisions based on analytical data and needed to trust it.
Do I need both observability data and data observability?
Most enterprises do. They address different stages of the data lifecycle and different teams. Observability data keeps infrastructure and security posture visible in real time, while data observability keeps analytical data products reliable. They complement each other rather than compete.
How does Cribl fit into observability data?
Cribl Stream is a vendor-agnostic pipeline that collects, reduces, enriches, normalizes, and routes observability data from any source and any destination. With Cribl Edge for distributed collection, Cribl Search for searching data in place, and Cribl Lake for tiered storage in open formats, it lets IT and security teams control their telemetry without vendor lock-in.