
Why does the "old" way of investigating a breach take so long?
The short answer is that every retrieval is all-or-nothing, and each step depends on someone else.
Say we've got a fictitious company, Sprockets, that uses its logging system to meet retention requirements. Older data gets "frozen" and must be "thawed" when needed. Sprockets has a security team that is separate from the logging team, so when security needs data restored, they have to ask logging to do it.
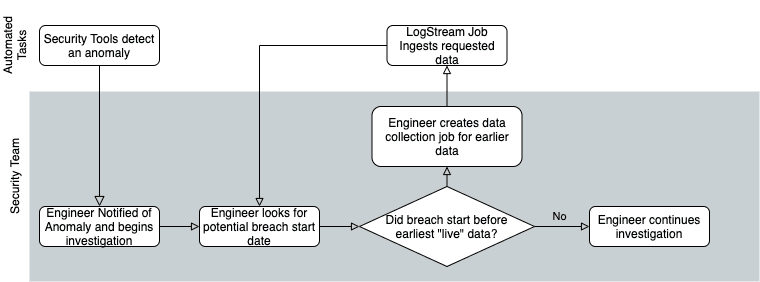
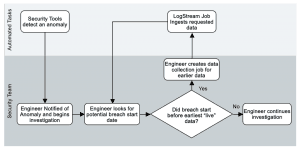
One morning, one of their security tools detects an anomaly and alerts the on-call security engineer. She starts digging through logs and realizes there has been a breach. It looks to involve three servers, a firewall pair, and a switch pair. After more digging, she realizes it started sometime earlier than the oldest data in the logging system.
Now the handoffs begin. The engineer asks the logging team to thaw earlier data archived in AWS S3. Because they need to retrieve all of the data for a given time window at once, she requests only a month. She waits for it to show up, checks it, and if the start of the incident isn't there, repeats the whole cycle. Every one of those requests is a ticket to another team, and the investigation slows to a crawl.
This is a common pattern, not a Sprockets-only problem. According to the SANS 2025 SOC Survey, 42% of SOCs dump all incoming data into a SIEM without a retrieval or management plan. The archive exists. Getting anything useful out of it is the hard part.
Why cheap storage alone doesn't fix breach investigations
Moving retention to low-cost storage saves a lot of money, but it does nothing on its own to get that data back when you need it. The traditional route of pulling frozen files whole, thawing them, and attaching them to your log system is simply too slow to produce meaningful answers quickly.
That matters more every year. With data privacy laws now in place and more on the way, the window for breach disclosure keeps tightening. Since Sprockets does business in the EU, they're on the clock for the mandated GDPR 72-hour notification window. No company wants to issue a breach notification without at least an idea of when the breach started and how many customers were exposed.
You need an approach that speeds up collection and lets you filter data before it crosses the wire. That reduces travel, decompression, and ingestion time. It also lowers the storage and ingest licensing you need to hold the data once it arrives.
How does Cribl Stream change the breach investigation workflow?
This is where Cribl Stream is useful. Place a Stream deployment between your logging sources and your analytics system, and you can archive everything to cheap storage for retention. That lets you reduce what goes into your logging system to just what you need day to day: filter unnecessary events, sample repetitive ones, and clean up messy data. Less stress on the logging system means better performance.
Replay in Stream is the other half of the equation. It gives you a way to retrieve data from the archive and filter it based on the partitioning scheme you chose when you wrote it. Let's revisit Sprockets to see what that looks like.
With 1TB/day of data, Sprockets can install and use the free version of Cribl Stream and move retention to cheap storage. With the money they're saving, they change their retention policy to keep log data around for 10 years.
Four years in, they discover evidence of a breach through firewall log analysis. Needing to work backward to find when it started, the security team runs a data collection job themselves. No ticket, no waiting on the logging team. And instead of downloading everything, they narrow it step by step:
Scope the job to only the last year of data, about 365TB.
Filter to just firewall logs, about 15% of total volume, or 54.75TB.
Because the partitioning scheme includes zone names, filter to only traffic between trusted and untrusted zones, less than 30% of firewall events, or about 16.5TB.
With a few filters, they've narrowed the replay to roughly 0.5% of the total archive. That is the difference between an investigation that takes days and one that takes hours.
Model the replay before you pull a single byte
Collection discovery, preview, and jobs let you model all of this before actually retrieving anything. Discovery shows you which files match your filters. Preview shows you sample events. Only then do you run the full job, confident it will pull just the data you need.
As the investigation progresses, the scope of the breach becomes clearer, and additional logs need to come back. Fire off another collection job for the new hosts, zones, or time ranges the moment you discover the need.
One multinational conglomerate uses this exact pattern with Amazon S3 as its first destination. In a recent investigation, the team replayed 1.335 PB of data from object storage and landed just 3.69 GB in Splunk, with about two hours for metadata discovery and four hours of processing. Full fidelity where it mattered, and nothing they didn't need.
Should you search before you replay?
Since I first wrote this the toolbox has grown; the answer is often yes.
Cribl Search can query data in place across Amazon S3, Azure Blob, and other object stores without moving or re-indexing it first. For a breach investigation, that means you can triage directly against the archive, confirm which hosts and time ranges matter, and then forward only those events to your SIEM with the send operator. If you want a deeper comparison, we've written up how Stream's Replay and Search's send differ.
Cribl Lake provides a telemetry-optimized store. Data lands in open formats, Replay works natively against it, and the security team gets access without filing a ticket with a cloud team for buckets or permissions. Search first, replay second, and the Sprockets engineer never has to wait on anyone.
Your archive should be evidence, not a dead end
Every breach investigation runs on the same clock: regulators want answers in 72 hours, and attackers often started long before you noticed. The architecture that wins is the one that separates where data lives from where it gets analyzed. Cribl's platform is built on that principle. Cribl's Data Engine for IT and Security lets you collect once, route a full-fidelity copy to the storage you choose, and send your SIEM only the data that earns its keep.
That separation gives security teams choice and control. Stream handles the real-time routing and Replay. Search queries the archive in place. Lake gives you a telemetry store you own, in open formats, with no rehydration queue. Together they turn frozen storage into live evidence, and they do it without adding agents, ripping out your SIEM, or locking your data into a proprietary format.
Sprockets is fictional, but the handoffs, the month-at-a-time thaws, and the ticking disclosure clock are not. If your breach investigation workflow still depends on another team's queue, put the security team in the driver's seat. Spin up the sandbox, point Stream at a bucket, and see how much of your next investigation you can finish before lunch.
Streamlining Your Breach Investigation FAQs
What is Replay in Cribl Stream?
Replay is the ability to collect data that Cribl Stream previously archived to object storage (Amazon S3, Azure Blob, Google Cloud Storage, or Cribl Lake) and send it back through a pipeline into any destination. You filter by time range and by the fields in your partitioning scheme to retrieve only the slice needed for an investigation.
Why is the traditional freeze-and-thaw approach so slow for breach investigations?
Frozen archives are usually retrieved whole, one time window at a time, and the request often has to go through a separate logging or platform team. Each cycle of request, wait, check, and repeat adds hours or days, which can cause problems meeting disclosure deadlines such as the GDPR 72-hour window.
How much data does Replay pull back?
That depends on how well you partition your archive. In the Sprockets example, filtering a year of logs down to firewall events between trusted and untrusted zones reduced the replay from 365 TB to roughly 16.5 TB, about 0.5% of the total. A real multinational customer replayed 1.335 PB from Amazon S3 and landed just 3.69 GB in Splunk.
Do I have to replay data to investigate it, or can I search it in place?
You can do either. Cribl Search can query data in object storage or Cribl Lake without moving it; this is a useful first step for triage. Once you know which events matter, you can use the send operator or a Stream Replay job to forward only those events to your SIEM.
Does partitioning matter for Replay?
Yes. Cribl Stream uses the directory structure of your archive, such as time, host, sourcetype, and zone, to exclude files before downloading them. A thoughtful partitioning expression is the difference between a targeted collection and a bulk download.
Can I try Replay without a license?
Yes. The Data Collection and Replay Sandbox provides a full standalone instance for practice. A free Cribl.Cloud account or download lets you process up to 1 TB per day at no cost.